Indice
Tipo di demo
| Generator | document_extraction_teacher 1.0.1 |
|---|---|
| Categoria | Document and Data Acquisition |
| Sorgenti | due PDF autentici per OCR e table extraction. |
1. Obiettivo
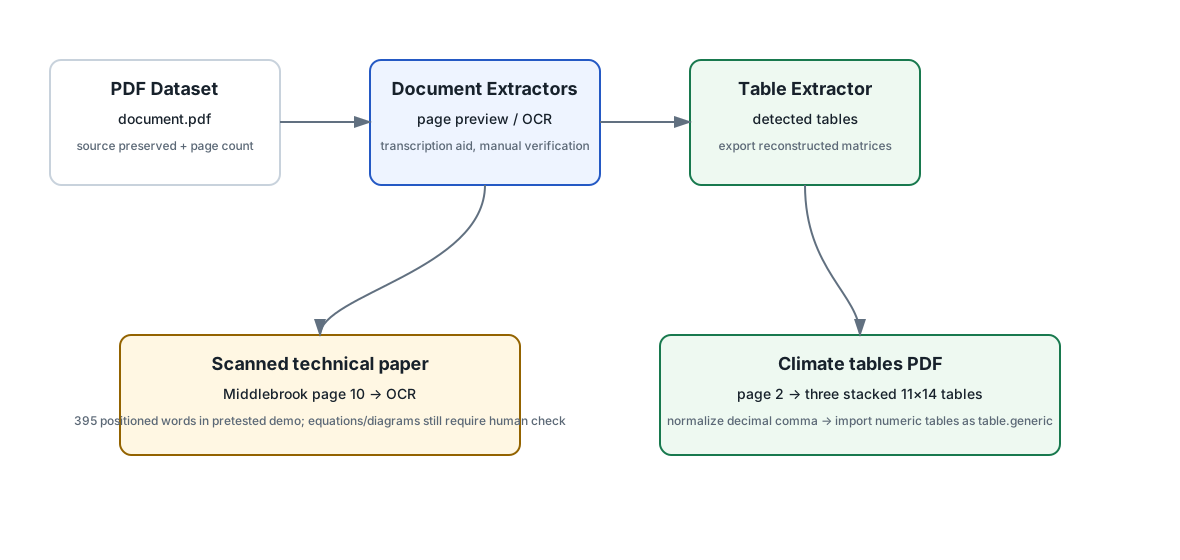
Mostrare che importare un PDF e ricavarne testo/tabelle sono fasi distinte. Il PDF resta un document.pdf autorevole; OCR e table extraction sono trasformazioni/strumenti successivi.
2. Paper tecnico scansionato
- Importare
middlebrook_loop_gain.pdfcomedocument.pdf. - Aprire Document Extractors.
- Preview page 10 con CORE OCR.
- Confrontare il testo riconosciuto con l'immagine originale.
Nel caso pretestato il demo ottiene 395 positioned words e la frase “loop gain”. Equazioni, subscripts e circuit diagrams vanno comunque verificati manualmente.
3. Climatic tables
- Importare
climate_tables.pdf. - Aprire page 2 nel Table Extractor.
- Il caso demo contiene tre tabelle 11×14 sovrapposte.
- Verificare headers, città e valori.
- Esportare, normalizzare il decimal comma e importare i risultati come
table.generic.
4. Rights boundary
Riferimento tecnico completo
Teacher guide
Teacher demonstration: document extraction
This private generator supplies two authentic PDF test cases. The separately provided executed DEMO Sessions contain OCR and table results, source images, Dataset notes and offline HTML.
Scanned technical paper
- Import
raw/middlebrook_loop_gain.pdfas adocument.pdfDataset. - Open Document Extractors and preview page 10 with CORE OCR. Compare the recognized words with the original page image.
- The pretested page yields 395 positioned words and the phrase “loop gain.” Verify equations, subscripts and circuit diagrams manually; OCR is a transcription aid.
The supplied Middlebrook paper is authorized only for this private teacher demonstration. Its redistribution rights were not established. Remove it from any later public package.
Climatic tables
- Import
raw/climate_tables.pdfas adocument.pdfDataset. - Preview page 2 in the Table Extractor viewer. CORE detects three stacked 11×14 tables.
- Check title, month headers, city names, January and annual values against the source image.
- Export each reconstructed table, normalize the decimal comma where
needed, and import normalized results as
table.genericDatasets.
The executed climatic-table DEMO publishes three separate nine-row numeric Datasets and preserves the raw matrices.
Generator README
Document Extraction teacher generator 1.0.0
Portable private GX-TXT Session Generator containing the two supplied PDF fixtures, pinned by SHA-256. It creates a fresh Session with the sources and teaching guide. The executed OCR and table DEMO Sessions are separate.
Rights and provenance
Source-use scope
middlebrook_loop_gain.pdf is a copyrighted technical
paper supplied by the user for a private teacher demonstration. The user
explicitly allowed this private use and said it must be removed from a
later public release. No general redistribution license is asserted.
climate_tables.pdf was supplied by the user as a
framework test and demonstration source. Its broader redistribution
rights have not been established. Keep it within the same private
teaching scope until verified.
Both originals are preserved byte for byte and individually
hash-pinned in generate.py.
Generator descriptor
; GX-TXT Session Generator API v1
[generator]
api_version=1
generator_id=document_extraction_teacher
name=Document extraction — teacher laboratory
category=Document and Data Acquisition
description=Teacher-only OCR and climatic-table extraction from two real supplied PDFs.
version=1.0.1
generator_type=python
entry_point=generate.py
author=Giux-Lab
tags=OCR;PDF;tables;climate;Middlebrook;teacher
required_capabilities=Python 3;GX-TXT Session
suggested_session_name=document-extraction-teacher
expected_purpose=Repeat the CORE OCR and Table Extractor workflows from authentic scanned and native-text PDFs.
files_produced=raw/middlebrook_loop_gain.pdf;raw/climate_tables.pdf;metadata/source_hashes.sha256;TEACHER_GUIDE.md